VCF 5.1.1 – Deploy an Edge Cluster in VCF environment

In our last blog post, we added a host to the workload domain. Let’s deploy an edge cluster.

By default, VCF bring-up process configures / prepares the NSX env for VLAN backed segment and it does not include edges / edge cluster. You must deploy and edge cluster for software define routing and network services.

Lets get some pre-requisites in place before we start,
We need couple of vlans configured on TOR to achieve an overlay networking,
Host Overlay Vlan – Host TEP
Edge Overlay Vlan – Edge TEP
2 Edge Uplink Vlans – To pair it with TOR for redundancy purposes.

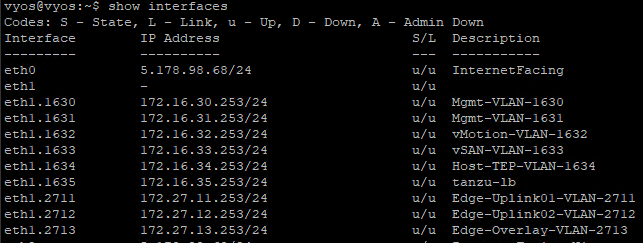
Following is vlan configuration on TOR,

Lets verify it on TOR,
Next,

Prepare the deployment parameters in an excel sheet,

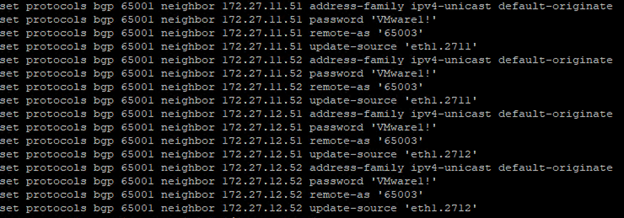
Next, Configure BGP on TOR,
Make sure to create a DNS record for edges and start the deployment,

SDDC Manager > Workload Domains> Click on 3 dots besides the name and “Add Edge Cluster”
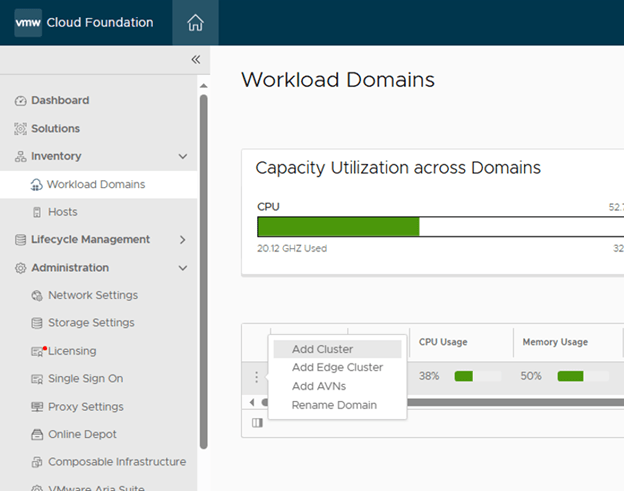
Check all Pre-requisites again and Begin,

Fill all the required details from parameters sheet that we created,

Additional cluster settings,

Kubernetes – Workload Management to create an NSX Edge cluster that complies with the requirements for deploying vSphere with Tanzu.

Application Virtual Networks to create an NSX Edge cluster that complies with the requirements deploying vRealize Suite components.

Custom if you want an NSX Edge cluster with a specific form factor or Tier-0 service high availability setting.

I have selected AVN here. You can select as per your use case.

Then the edge node settings, Type each edge node information and click “ADD EDGE NODE”at the end.

Verify the information on next page,

Node 1 details,
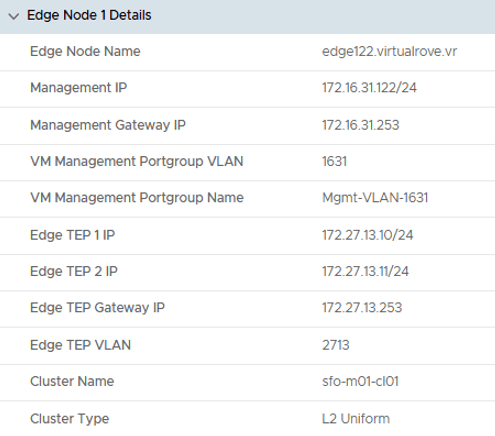
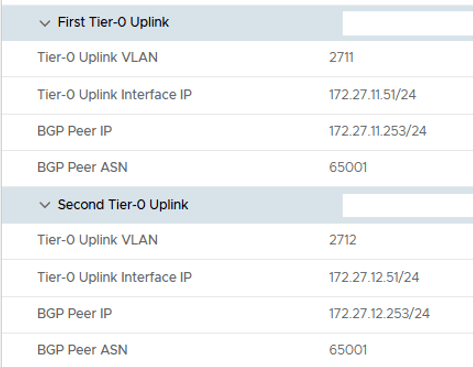
Node 1, Uplink details,
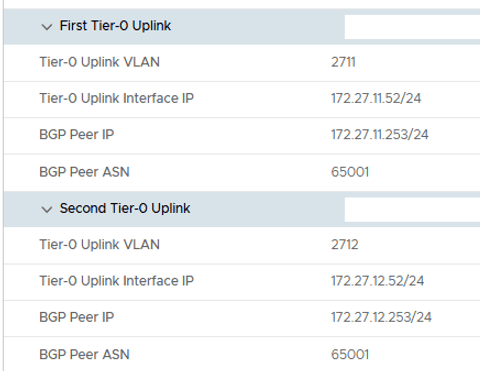
Node 2 details,

Node 2, Uplink details,
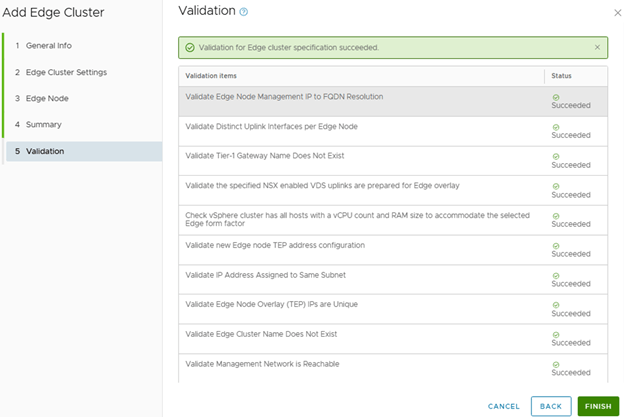
Review and fix any issues reported by validation and Finish,
Monitor the “Adding edge cluster vr-edge-cluster-01” in SDDC task details,

Task is successful and we see the edge cluster in SDDC UI,

On a high level, this workflow configures following…

Created 2 uplink port groups on vCenter VDS,

Two edges have been deployed,

Edge Cluster is created,

Transport Zone for edge vlan have been created,

Edge uplink profile have been created,

Both nodes have all these settings configured,

Active-Active Tier-0 gateway has been deployed,

VLAN Backed uplink segments has been deployed to use it in interfaces configuration,

All interfaces looks good,
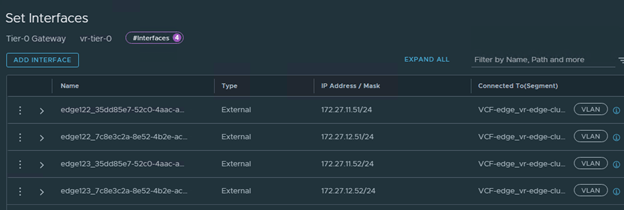
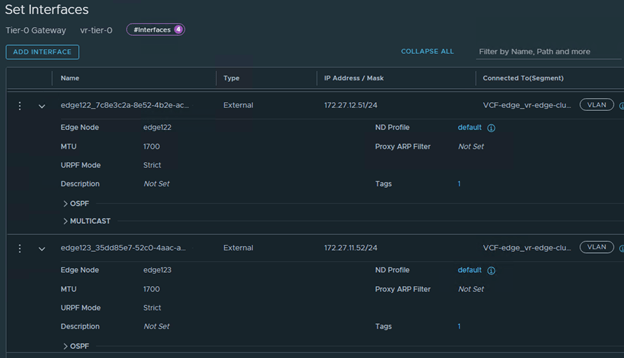
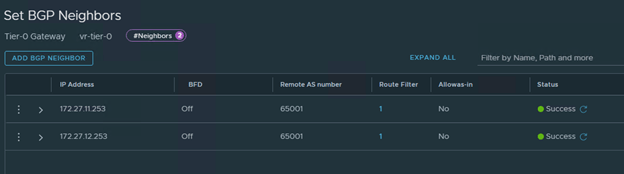
BGP is tuned on and 2 Neighbors configured,

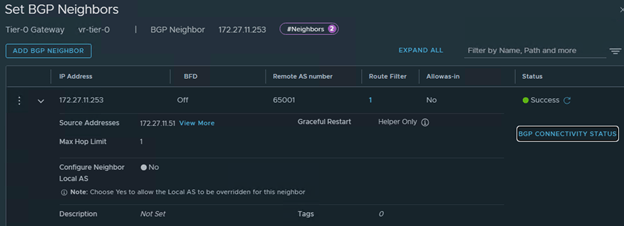
Check the BGP Connectivity status, Shows Established for both edges,

Route-Redistribution is in place,
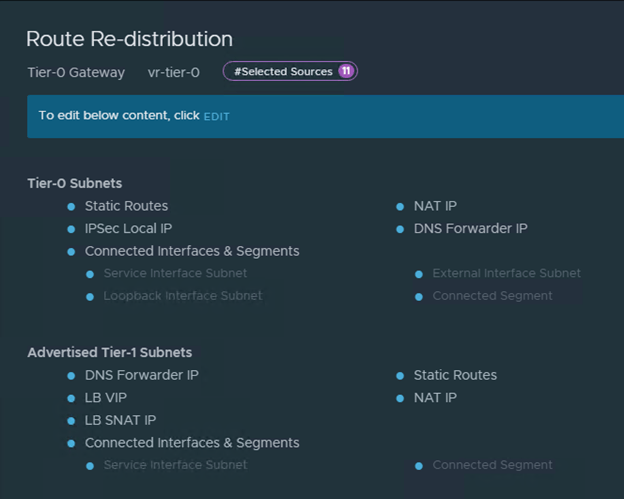
And it has also deployed a Tier-1 gateway and connected to T-0,

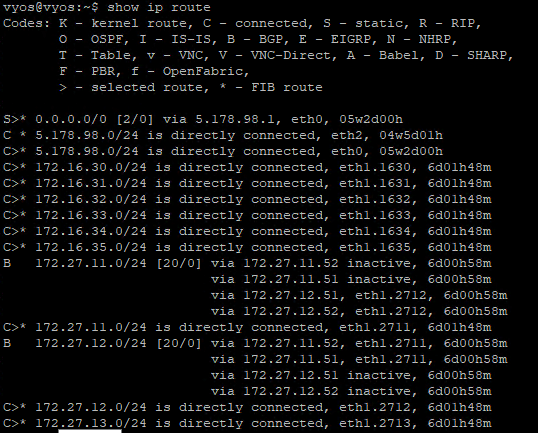
Wow, everything looks good. Lets check the BGP routes on the TOR,

All 4 BGP Neighbors shows up on the TOR,

BGP Routes looks good,
Nice.

Let’s create a test segment with 192.168.X.X CIDR and check if it appears in BGP route on TOR,

New segment has been created,

And we see the new route on TOR,

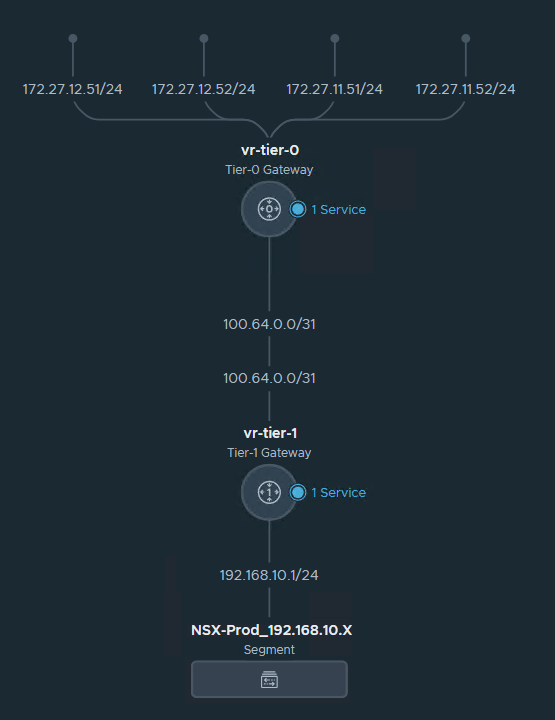
Here is how my network topology looks in NSX,
Hurray…!!!

All looks good. We are good to attach new VM’s to this overlay backed segment and it would get the connectivity to rest of the world.

That concludes the adding edge cluster task.

Are you looking out for a lab to practice VMware products…? If yes, then click here to know more about our Lab-as-a-Service (LaaS).

Leave your email address in the box below to receive notification on my new blogs.
VCF 5.1.1 – Add a new host to an existing Workload Domain

Let’s get started with some documentation around adding / commissioning new host in an existing workload domain.

Add a Host to a vSphere Cluster Using the SDDC Manager UI

Verify that a host is available in the SDDC Manager inventory. For information on commissioning hosts, see Commission Hosts.

Commission Hosts

  • Hosts that use vSAN storage can only be used with vSAN-based workload domains.
  • Hosts that use NFS storage can only be used with NFS-based workload domains.
  • Hosts that use VMFS on FC storage can only be used with VMFS on FC-based workload domains.
  • Hosts that use vVols storage can only be used with vVols-based workload domains.

Ensure that a network pool supports the storage type you select for a host (vSAN, NFS, VMFS on FC, vVols).

Commissioning a host adds it to the VMware Cloud Foundation inventory. The host you want to commission must meet the checklist criterion below.

Ensure that each host you are commissioning meets the following criteria:

  • Hosts for vSAN-based workload domains are vSAN-compliant and certified on the VMware Hardware Compatibility Guide.
  • Hosts for NFS-based workload domains are certified on the VMware Hardware Compatibility Guide.
  • Hosts for VMFS on FC-based workload domains are certified on the VMware Compatibility Guide. In addition, the hosts must have supported FC cards (Host Bus Adapters) and drivers installed and configured. For compatible FC cards, see the VMware Compatibility Guide.
  • Hosts for vVols-based workload domains are certified on the VMware Hardware Compatibility Guide.
    • For vVols on FC-based workload domains, ensure that all ESXi hosts have access to the FC array before launching the workflow.
    • For vVols on NFS-based workload domains, ensure that all ESXi hosts must be able to reach the NFS server from the NFS network assigned in the IP pool.
    • For vVols on iSCSI-based workload domains, ensure that the iSCSI software initiator must be enabled on each ESXi host and the VASA provider URL must be listed as the dynamic target.
  • Two NIC ports with a minimum 10 Gbps speed. One port must be free, and the other port must be configured on a standard switch. This switch must be restricted to the management port group.
  • Host has the drivers and firmware versions specified in the VMware Hardware Compatibility Guide.
  • A supported version of ESXi is installed on the host. See the VMware Cloud Foundation Release Notes for information about supported versions.
  • DNS is configured for forward and reverse lookup and FQDN.
  • Host name must be same as the FQDN.
  • Self-signed certificate regenerated based on FQDN of host.
  • Management IP address is configured on the first NIC port.
  • Host has a standard switch and configured with 10 Gbps speed default uplinks starting with vmnic0 and increasing sequentially.
  • Hardware health status is healthy without any errors.
  • All disk partitions on HDD and SSD are deleted.
  • Network pool must be created and available before host commissioning.
  • Hosts for the vSAN-based workload domain must be associated with the vSAN enabled network pool.
  • Hosts for the NFS-based workload domain are associated with the NFS enabled network pool.
  • Host is configured with an appropriate gateway. The gateway must be part of the management subnet.

Before we get started, Here is new host config that will get added to existing management vi workload domain.

Hostname: esxi124.virtualrove.vr
Memory: 16 GB
pNICS: 2
Disks: 20gb 100gb 100gb , Total 220 RAW storage which will get added to existing VSAN storage.
VM network vlan changed to VLAN 1630
NTP settings updated to use NTP server as “172.16.31.110”
SSH and NTP service configured to “Start and Stop with the host”
And regenerated self-sign certs for esxi. I have listed steps to regenerate in my previous blogs.

Login to SDDC Manager > Hosts > Commission Hosts,

Make sure all pre-requisites are met, Select All,

Next,
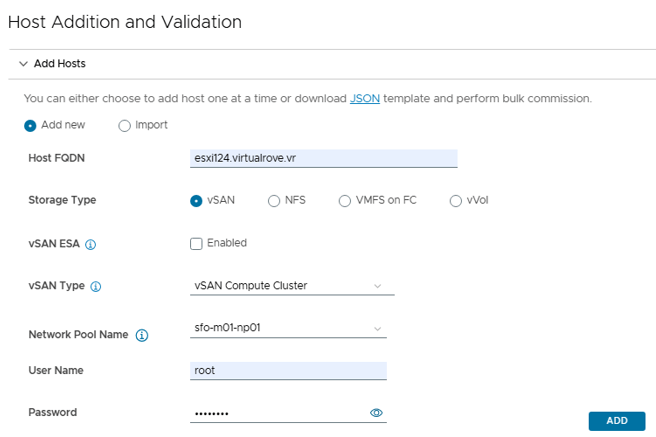
Enter the required information and click on ADD

I have unchecked vSAN ESA, since am not using VSAN ready nodes as well as NO vLCM images.
vSAN ESA is only supported in workload domains that use vLCM images.

vSAN Type is vSAN Compute Cluster.

Also, Select the existing “Network Pool” from the drop-down menu for vMotion & VSAN network,

Same can be verified on on SDDC manager under “Network Settings”

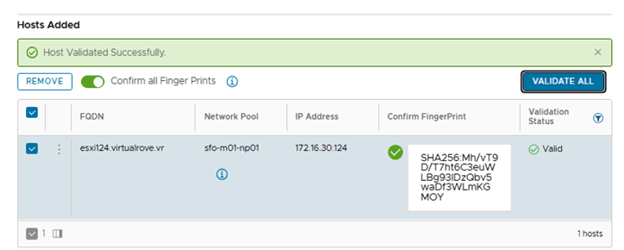
Once the host has been added, Turn on the radio button “Confirm All Finger Prints” and “VALIDATE ALL”

Review & Finish,

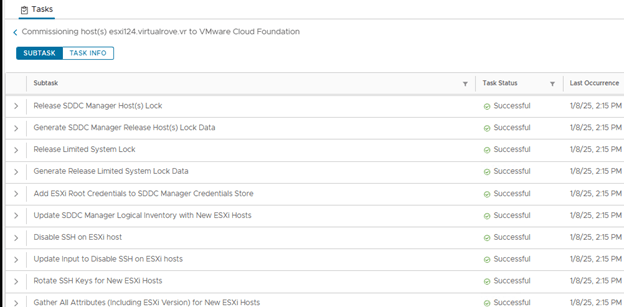
Monitor “ Commissioning host(s) esxi124.virtualrove.vr to VMware Cloud Foundation” task in SDDC task list,

Once finished, host will appear in the “UNASSIGNED HOSTS”

Lets get the new host added to the existing management vi domain after commissioning it,
SDDC UI > Select Management Workload Domain > Clusters Tab > Click 3 dots to “ADD Hos”

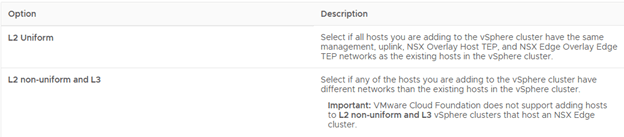
Select the commissioned host and select “L2 Uniform”

Important: VMware Cloud Foundation does not support adding hosts to L2 non-uniform and L3 vSphere clusters that host an NSX Edge cluster.

Finish.

Monitor the “Adding new host(s) to cluster” in SDDC task list,

On a high level, following steps are performed in “Adding new host to cluster”,

After initial validation, it adds the host to the cluster,
Adds host to VDS
Configures all vmknics
Removes STD switch
Configures HA
Adds it to NSX by adding required transport zone as per the TNP and prepares it for NSX.
And finally makes it available for workload migration / new workload.

Let’s review the environment after adding the host.

Host & Clusters view with all vmknics,

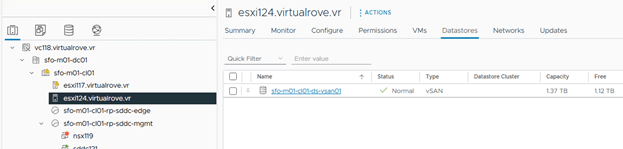
VSAN Storage added to existing cluster,

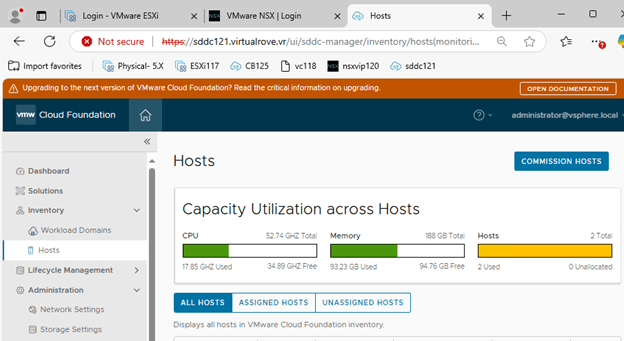
Hosts on SDDC Manager,

Workload domain host view,

New host has been prepared for NSX and ready for vlan backed segment,

That’s it for this post. Hope that it was helpful. We will add an edge cluster in our next blog.

Are you looking out for a lab to practice VMware products…? If yes, then click here to know more about our Lab-as-a-Service (LaaS).

Leave your email address in the box below to receive notification on my new blogs.

VMware VCF 5.2 – Onboarding existing vSphere infra into VCF

With vCloud Foundation 5.2 version, you can import / convert your existing vSphere infrastructure as well as NSX env into the VCF and start managing it from SDDC manager.

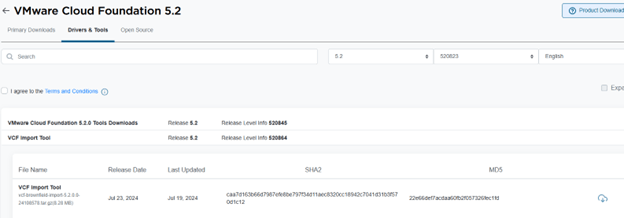
VCF import tool will help to achieve the same. The download link can be found here,

Download

Let’s discuss some prerequisites before we move on,

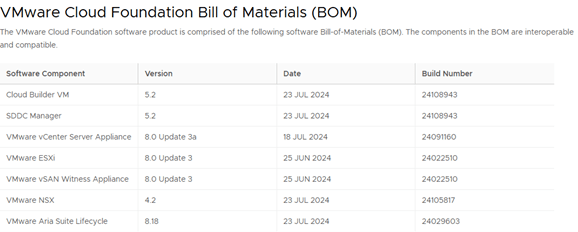
Existing vSphere versions should be aligned with VCF 5.2 BOM. (ESXi & vCenter)
No standard switch supported.
DRS should be in fully automated mode and HA enabled on the cluster.
Common / Shared storage between the hosts. (VSAN skyline health check compatible or with NFS3 version or FC storage)
VDS should have physical uplinks configured.
vCenter & SDDC Manager should be installed in the same cluster that we are converting. SDDC manager can be downloaded from the same location as VCF import tool.
Cluster with vCenter should have minimum of 4 hosts.

Here is the VCF 5.2 BOM for your reference,

Let’s get into lab and review the existing env,

I have a 4 hosts VSAN cluster with vCenter and SDDC installed in it. Remember, VSAN is not a requirement for this setup.

Review the ESXi & vCenter version,

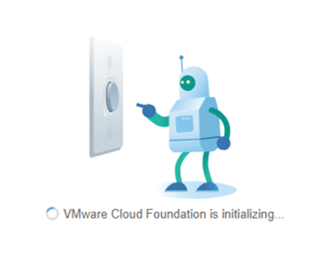
SDDC manager installation is pretty simple and straightforward. You just need to download the ova and import it into the cluster. It will ask for some common parameters like hostname, ip schema & passwords for defined users. Once the SDDC boots up, you will see this on the screen of SDDC url,

“VMware Cloud Foundation is initializing… ”

Additionally, I have one single vds with 2 uplinks and some common port groups configured,

Let’s get into action and start working on getting this env into VCF.

WinSCP to SDDC appliance using VCF user and upload the VCF Import tool to vcf directory on SDDC,

Next, SSH to SDDC appliance,

Check the if the file has been uploaded and then extract the tar file using ‘ tar xvf’ command,

You will see multiple files getting extracted in the same directory,

Next, get into the ‘vcf-brownfield-toolset’ directory to run further commands,

The python script (vcf_brownfield.py) is located under “vcf-brownfield-toolset” directory.

We need to runt this script using some additional parameters,

python3 vcf_brownfield.py convert –vcenter {vcenter-fqdn} –sso-user administrator@vsphere.local –domain-name {WLD-Name} –nsx-deployment-spec-path {NSx-Specifications-JOSN-Path} OR –skip-nsx-deployment

Replace the parameters to match with your env. And check the env compatibility by changing the parameter to “check” instead of “convert”.

“CHECK” – Checks whether a vCenter is suitable to be imported into SDDC Manager as a workload domain.

python3 vcf_brownfield.py check –vcenter vcfvc182.virtualrove.local –sso-user administrator@vsphere.local –domain-name imported-vcf –skip-nsx-deployment

All other supported parameters can be found here,

https://docs.vmware.com/en/VMware-Cloud-Foundation/5.2/vcf-admin/GUID-44CBCB85-C001-41B2-BBB4-E71928B8D955.html

I am skipping the nsx part of it by adding “–skip-nsx-deployment” towards the end of the command.

Next, script needs vCenter SSO credentials

Confirm thumbprint,

Monitor the script,

After finishing all required checks, it loads the summary,

As we can see, 2 checks have been failed out of 89. It has also generated CSV file on SDDC manager. Lets have look at the logs and fix things as needed,

On SDDC manager, navigate to Output folder and download the CSV file,

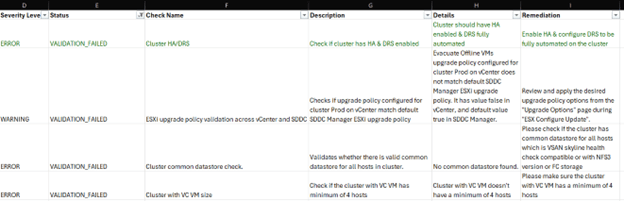
The downloaded CSV file is easy to read, It shows the issue description and remediate it,

here is the sample…

Apply the filter for ‘Status’ column to see ‘VALIDATION_FAILED’.

As we see, it is complaining about HA / DRS being disabled on the cluster. I did that on purpose.
And the next one is ‘WARNING’ and not an ‘ERROR’. However, found following article which talks about that warning,

“ESXi upgrade policy validation across vCenter and SDDC Manager”  

ESX Upgrade Policy Guardrail Failure

https://docs.vmware.com/en/VMware-Cloud-Foundation/5.2/vcf-admin/GUID-458B6715-3ED6-4423-B093-64B1A2963CC0.html

This issue causes a warning only. You can proceed with the convert or import process without remediating the issue.

Hence, fixed the HA and ran the ‘CONVERT’ command,

Imp Note: Remember to take a snapshot of SDDC Manager before you run the CONVERT command.

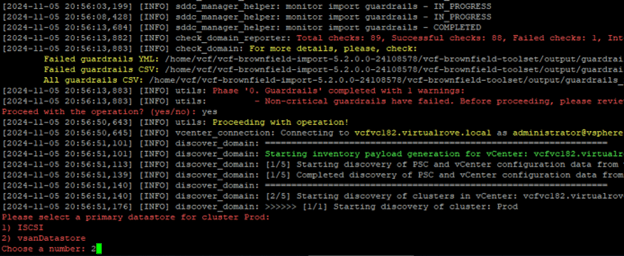
Next, we can see that one check is failed and it still gave an option to move on,

Next, we get an option to select primary storage for VCF env. I had iSCSI datastore too,

Final confirmation and the game begins,

Monitor the green parent tasks,

Populating inventory in SDDC,

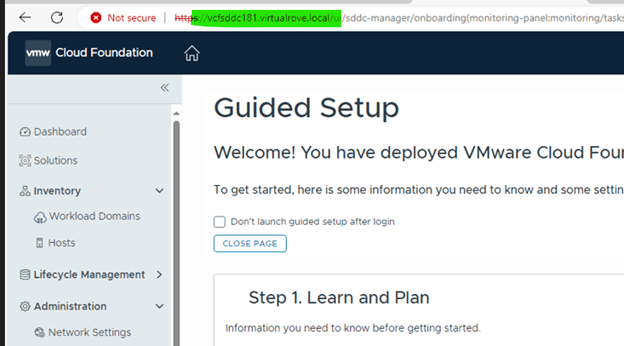
Navigating to SDDC Manager URL,

You will also notice a task in progress on SDDC Manager, ‘Initialize Imported Domain’

Click on the task to check details. It will help you to troubleshoot if something breaks,

Lets check the vCenter once all tasks have been completed. Notice that the vCenter inventory has a new resource pool.

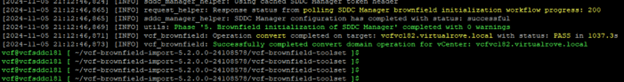
Script shows completed on SDDC manager ssh session.

Review the SDDC UI,


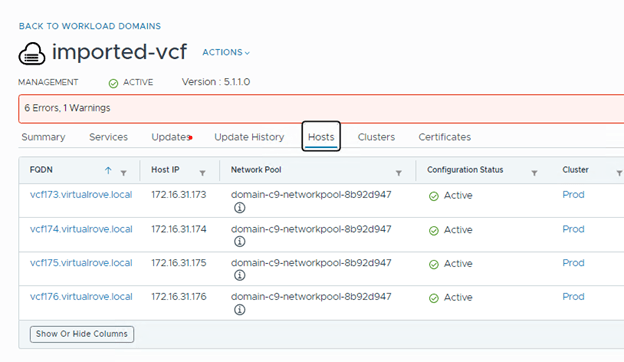
“imported-vcf” that’s the name of the domain we had specified in the script,

Hosts,

We have successfully converted our existing vSphere env into the VCF.

Next, You can plan on getting NSX configured in the management domain and then additional VI Workload Domains.

Before we finish, wanted to share some more reports (guardrails_report_vcf) from failed VCF validation.

Well, that’s all I had for this post. Stay tuned for next couple of blogs on VCF.

Detailed information on available operation in python script can be found here,

https://docs.vmware.com/en/VMware-Cloud-Foundation/5.2/vcf-admin/GUID-6EEE731E-C3C4-40AD-A45D-5BAD2C4774AB.html

When you are using the VCF Import Tool, certain guardrail messages may require you to perform a manual update to the SDDC Manager database. If you encounter any of these guardrail issues, modify the example commands to resolve the issues.

https://docs.vmware.com/en/VMware-Cloud-Foundation/5.2/vcf-admin/GUID-BE0B38BC-8A4C-470E-B676-1B85D3C840F0.html

Thank You.

Are you looking out for a lab to practice VMware products…? If yes, then click here to know more about our Lab-as-a-Service (LaaS).

Leave your email address in the box below to receive notification on my new blogs.
NSX-T Upgrade from v3.2.2 to v4.1 Failed – Connection between host 473cc672-2417-4a97-b440-38ab53135d02 and NSX Controller is UNKNOWN.

Got following error while upgrading NSX from v3.2.2 to v4.1.

Pre-upgrade checks failed for HOST: Connection between host 473cc672-2417-4a97-b440-38ab53135d02 and NSX Controller is UNKNOWN. Response : [Lcom.vmware.nsxapi.fabricnode.dto.ControlConnStatusDto;@edbaf5b Connection between host 473cc672-2417-4a97-b440-38ab53135d02 and NSX Manager is UNKNOWN. Please restore connection before continuing. Response : Client has not responded to heartbeats yet

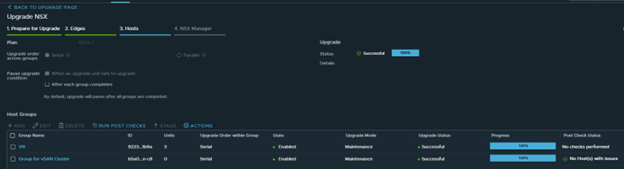
We only have 3 hosts in the cluster. For some reason, it was showing 4th host “esxi164” in host groups which does not exist in the vCenter inventory.

Click on the host group to check the details.

Here is my vCenter inventory,

The host in the question (esxi164.virtualrove.local) was one of the old host in the cluster. It was removed from the cluster long back. However, somehow it is showing up in NSX upgrade inventory.

And as the error message says, NSX-T manager was unable to locate this to upgrade it.

“Connection between host 473cc672-2417-4a97-b440-38ab53135d02 and NSX Manager is UNKNOWN.”

The UUID mentioned in the error message had to be for missing host (esxi164.virtualrove.local). Because the UUID was not matching with any of the host transport nodes UUID in the cluster. You can run the following command on one of the NSX manager to get the UUID’s of the nodes.

get transport-nodes status

Or you can click on the TN node in NSX UI to check the UUID.

If you click next on the upgrade page, it will not let you upgrade NSX managers.

So, the possible cause for this issue is, the old host entry still exists in the NSX inventory somewhere. And it is trying to locate that host to upgrade it.

There is an API call to check the state of the host.
GET https://{{MPIP}}/api/v1/transport-nodes/<Transport-Node-UUID>/state

Replace the MPIP (NSX manager IP) and TN UUID to match with your env.
GET https://172.16.31.168/api/v1/transport-nodes/473cc672-2417-4a97-b440-38ab53135d02/state

As we can see from the output, “current_step_title: Preparing Installation”. Looks like something went wrong while the host was being removed from NSX env and its state is still being marked as “state: pending” in NSX manager database.

Lets delete the host entry by using an API call,
DELETE https://172.16.31.168/api/v1/transport-nodes/473cc672-2417-4a97-b440-38ab53135d02?force=true&unprepare_host=false

Status: 200 OK

Run the GET API again to confirm,

It does not show any information now.

Time to check the upgrade console in NSX.

The group which was showing 1 host with an error no longer exists.

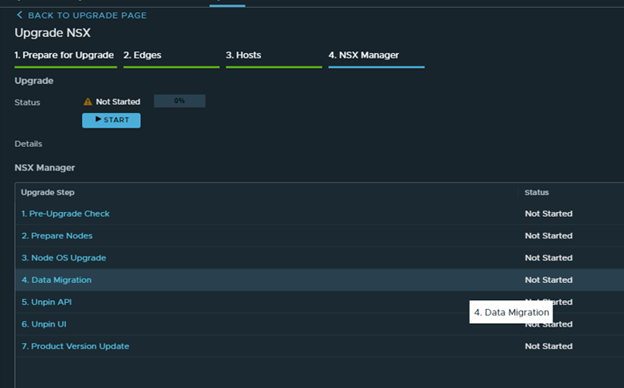
I was able to get to the next step to upgrade NSX managers.

Confirm and start.

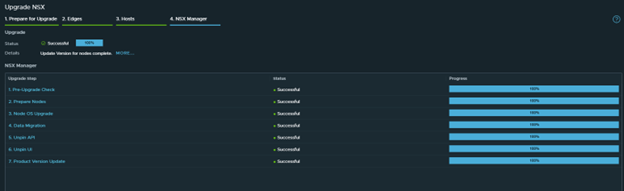
Upgrade status.

As stated in the message above, ran “get upgrade progress-status” in the cli.

NSX upgrade to v4.1 has been successfully completed.

That’s all for this blog. Hope that the information in the blog is helpful. See you in the next blogpost. Thank You for visiting.

Are you looking out for a lab to practice VMware products…? If yes, then click here to know more about our Lab-as-a-Service (LaaS).

Leave your email address in the box below to receive notification on my new blogs.

NSX-T: Replace faulty NSX Edge Transport Node VM

I recently came across a situation where the NSX-T Edge vm in an existing cluster was having issues while loading its parameter. Routing was working fine and there was no outage as such. However, when a customer was trying to select an edge vm and edit it in NSX UI, it was showing an error. Support from VMware said that the edge in question is faulty and needs to be replaced. Again, routing was working perfectly fine.

Let’s get started to replace the faulty edge in the production environment.

Note: If the NSX Edge node to be replaced is not running, the new NSX Edge node can have the same management IP address and TEP IP address. If the NSX Edge node to be replaced is running, the new NSX Edge node must have a different management IP address and TEP IP address.

In my lab env, we will replace a running edge. Here is my existing NSX-T env…

Single NSX-T appliance,

All hosts TN have been configured,

Single edge vm (edge 131) attached to edge cluster,

One test workload overlay network. Segment Web-001 (192.168.10.0/24)

A Tier-0 gateway,

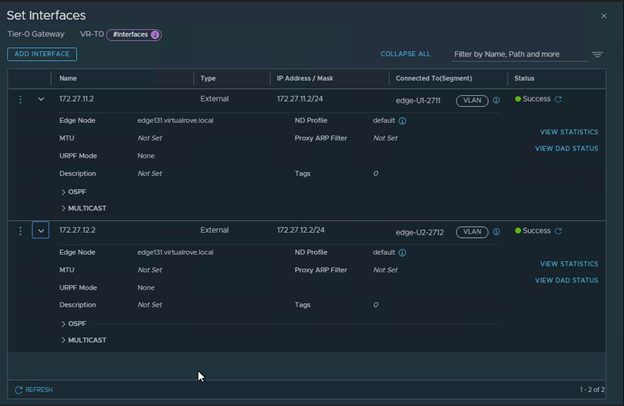
Note that the interfaces are attached to existing edge vm.

BGP config,

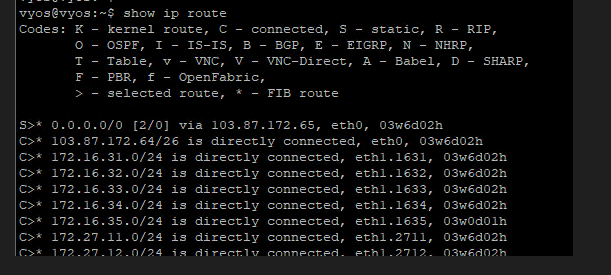
Lastly, my VyOS router showing all NSX BGP routes,

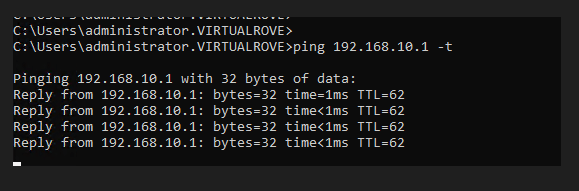
Start continuous ping to NSX test overlay network,

Alright, that is my existing env for this demo.

We need one more thing before we start the new edge deployment. The new edge vm parameters should match with the existing edge parameters to be able to replace it. And the existing edge showing an error when we try to open its parameters in NSX UI. The workaround here is to make an API call to existing edge vm and get the configuration.

Please follow the below link to know more about API call.

NSX-T: Edge Transport Node API call

I have copied the output to following txt file,

EdgeApi.txt

Let’s get started to configure the new edge to replace it with existing edge. Here is the link to the blogpost to deploy a standalone edge transport node.

NSX-T: Standalone Edge VM Transport Node deployment

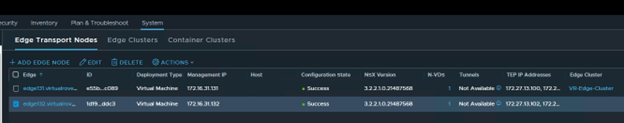
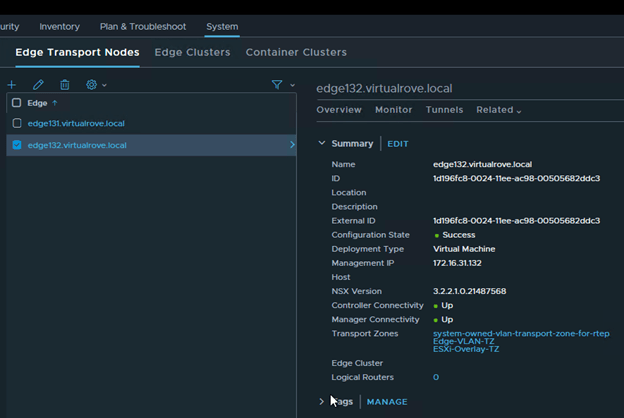
New edge vm (edge132) is deployed and visible in NSX-T UI,

Note that the newly deployed edge (edge132) does not have TEP IP and Edge cluster associated with it. As I mentioned earlier, The new edge vm parameters should match with the existing edge parameters to be able to replace it.

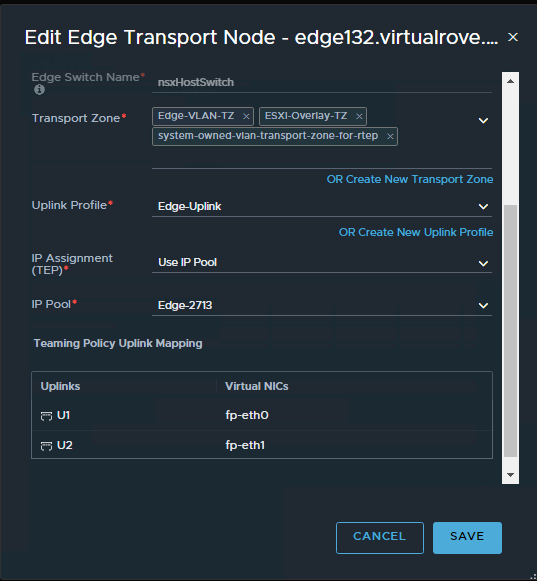
Use the information collected in API call for faulty edge vm and configure the new edge vm the way you see it in the API call. Here is my new edge vm configuration looks like,

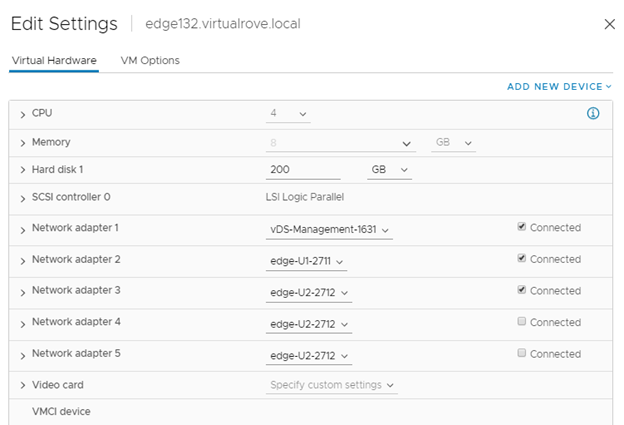
Make sure that the networks matches with the existing non working edge networks.

You should see TEP ip’s once you configure the new edge.

Click on each edge node and verify the information. All parameters should match.

Edge131

Edge132

We are all set to replace the faulty edge now.

Select the faulty edge (edge131) and click on actions,

Select “Enter NSX Maintenance Mode”

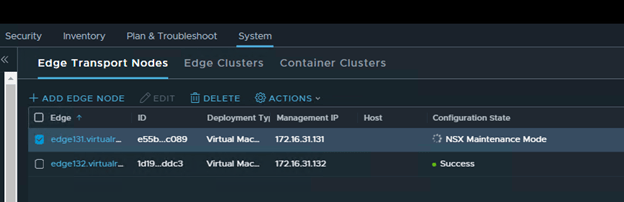
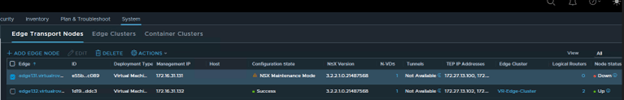
You should see Configuration State as “NSX Maintenance Mode” in the UI.

And you will lose connectivity to your NSX workload.

No BGP route on the TOR

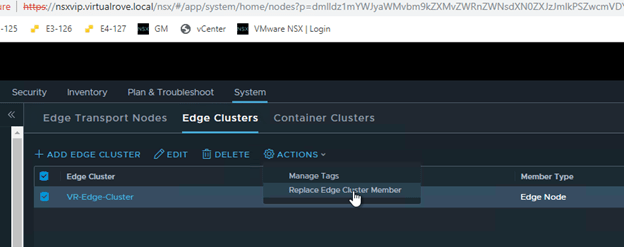
Next, click on “Edge Clusters”, Select the edge cluster and “Action”.

Choose “Replace Edge Cluster Member”

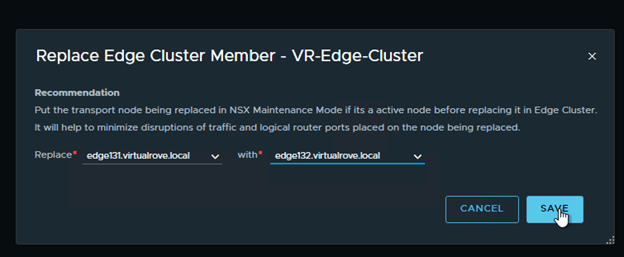
Select appropriate edge vm’s in the wizard and Save,

As soon as the faulty edge have been replaced, you should get the connectivity to workload.

BGP route is back on the TOR.

Interface configuration on the Tier-0 shows new edge node.

Node status for faulty edge shows down,

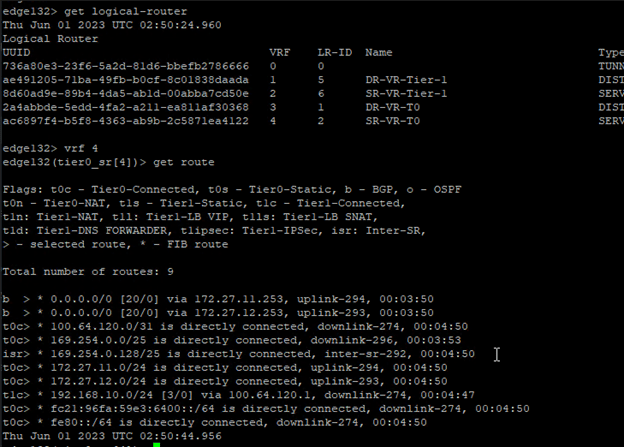
Let’s get into the newly added edge vm and run “get logical-router” cmd,

All service routers and distributed routers have been moved to new edge.

Get into the SR and check routes to make sure that it shows all connected routes too,

We are good to delete the old edge vm.

Lets go back to edge transport node and select the faulty edge and “DELETE”

“Delete in progress”

And its gone.

It should disappear from vCenter too,

Well, that was fun.

That’s all I had to share from my recent experience. There might be several other reasons to replace / delete existing edge vm’s. This process should apply to all those use cases. Thank you for visiting. See you in the next post soon.

Are you looking out for a lab to practice VMware products…? If yes, then click here to know more about our Lab-as-a-Service (LaaS).

Leave your email address in the box below to receive notification on my new blogs.

NSX-T: Edge Transport Node API call

Welcome back techies. This is going to be the short one. This article describes the steps to make an API call to NSX edge transport node vm to get the edge configuration. At the time of writing this blog, I had to collect this information to replace the faulty edge node vm in the env.

Here is the API call,
GET https://<nsx-manager-IP>/api/v1/transport-nodes/tn-id .

Replace nsx manager ip and tn-id with your edge vm id in nsx env.

https://172.16.31.129/api/v1/transport-nodes/e55b9c84-7449-477a-be42-d20d6037c089

To get the “tn-id” for existing faulty edge, login to NSX > System> Nodes and select existing faulty edge

You should see ID on the right side,

If NSX UI is not available for any reason, ssh to nsx-t manager using admin credentials and run following command to capture the UUID / Node ID

get nodes

This is how the API call and output looks like,

Send the API call to get the output shown in the body. This output contains entire configuration of the edge vm in script format.

That’s all for this post. Thank You.

Are you looking out for a lab to practice VMware products…? If yes, then click here to know more about our Lab-as-a-Service (LaaS).

Leave your email address in the box below to receive notification on my new blogs.

NSX-T: Standalone Edge VM Transport Node deployment

There can be multiple reasons to deploy nsx-t edge vm via ova instead of deploying thought nsx-t manager. At the time of writing this blog, I had to deploy edge vm via ova to replace faulty edge vm in nsx-t env. You may be deploying one to create a Layer 2 Bridge between nsx-v and nsx-t env to migrate workload.

Alright. Let’s start deploying an edge vm without using nsx-t manager UI.

To begin with, you need to manually download edge vm ova from VMware downloads page here…

Make sure to match the version with your existing NSX-T env.

Once downloaded, login to vSphere web client and start deploying an ova template. It’s straightforward like any other generic ova deployment. Make sure to select the exact same networks that are attached to your existing faulty edge vm.

In my case, 1st vmnic is attached to management network and next 2 are attached to uplink1 & uplink2 network respectively. Rest all nic cards remains unchecked.

Next, you will need to enter the NSX-T manager information in “Customize Template” section of the deployment.

Enter the Manager IP & Credentials.
NO need to enter “Node ID”.

You also have an option to leave this blank and join it to NSX-T control plane once the appliance is up and running. For now, I am entering all these details. Will also discuss on manually attaching edge vm to nsx-t manager control plane.

To get the NSX-T manager thumbprint. SSH to NSX-T manager and run following command,

get certificate api thumbprint

You can also get the thumbprint from the following location in the UI.

Login to NSX-T manager and click on view details,

Enter remaining network properties in the deployment wizard and finish.

Once the VM is up and running, you will see it in NSX-T UI here,

You will not see newly added edge vm here If you did not enter NSX-T thumbprint information in the deployment wizard. To manually join newly created edge vm to nsx-t manger control plane, run following command on the newly created edge vm.

Edge> join management-plane <Manager-IP> thumbprint <Manager-thumbprint> username admin

Same process has been described in following VMware article.

https://docs.vmware.com/en/VMware-NSX-T-Data-Center/3.2/migration/GUID-8CC9049F-F2D3-4558-8636-1211A251DB4E.html

Next, the newly created edge vm will not have N-VDS, TEP or Tranport Zones configuration. Further configuration will be specific to individual use case.

That’s all for this post.

Are you looking out for a lab to practice VMware products…? If yes, then click here to know more about our Lab-as-a-Service (LaaS).

Leave your email address in the box below to receive notification on my new blogs.
NSX-T How to change the Cluster VIP

This is short one, but someone might spend good amount of time to search for possible solution. If you have 3 local mangers cluster and VIP has been set already. Then you realized that there was a typo and the VIP address needs to be changed.

NSX-T GUI does not allow cluster VIP to be changed or removed.

The possible solution that anyone can think of is API call. However, its simpler than that. You need to login to one of the Local Manager in a cluster to change or remove the VIP.  😊

In my case, I logged into https://172.16.31.129/nsx/#/app/home/overview

Hope that helps. Thank You.

Are you looking out for a lab to practice VMware products…? If yes, then click here to know more about our Lab-as-a-Service (LaaS).

Leave your email address in the box below to receive notification on my new blogs.

NSX-T Federation – How to remove the location from GM

We ran into a situation where we had to remove the Local Manager from Global Manager. I replicated this in the lab env. It’s straightforward. However, there are couple of points that need to be addressed before you delete / remove the Local Manager from Global Manager.

Removing location from GM removes all objects created from GM.

Here is what my existing config looks like,

I have one Tier-1 gateway created from global manager, which is specific to Site-A

A segment which is attached to above Tier-1 GW.

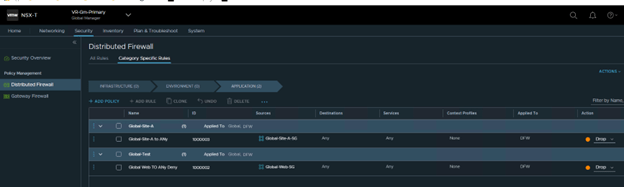
Some rules and policies created on the global level.

Notice that all globally created rules get a Rule ID starting from one million.

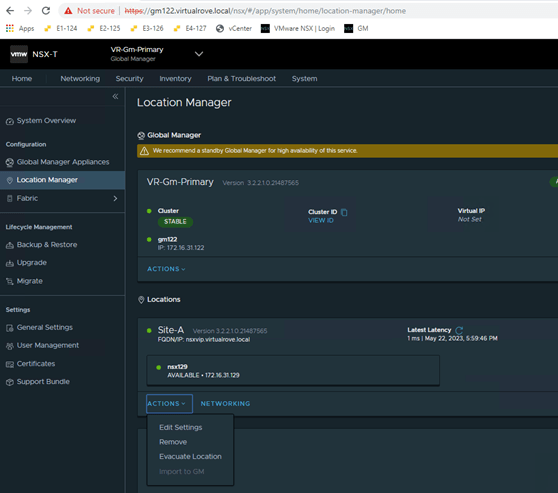
Navigate back to location manager, Click on ‘Action’ for the site to be removed and then ‘Remove’

Check the prompt,

Note: If you have any location-specific configurations created from the Global Manager for this location — such as Tier-0 gateways — you must first remove these configurations manually before proceeding.

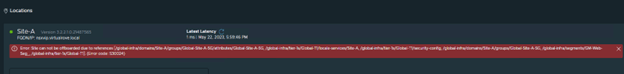
Error: Error: Site can not be offboarded due to references [/global-infra/domains/Site-A/groups/Global-Site-A-SG/attributes/Global-Site-A-SG, /global-infra/tier-1s/Global-T1/locale-services/Site-A, /global-infra/tier-1s/Global-T1/security-config, /global-infra/domains/Site-A/groups/Global-Site-A-SG, /global-infra/segments/GM-Web-Seg_, /global-infra/tier-1s/Global-T1]. (Error code: 530024)

Basically, you want to make sure that all objects that are created from GM are deleted before you perform this operation.

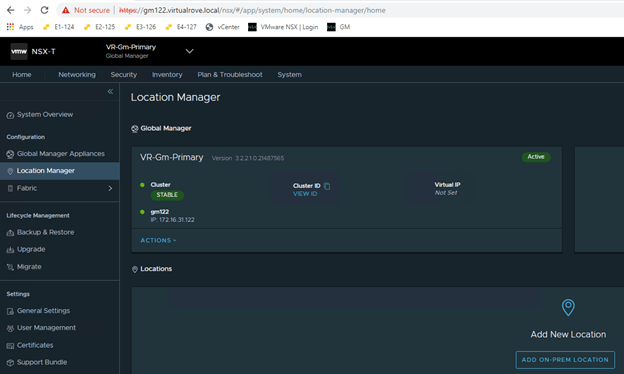
I deleted all T-1’s and Segments from GM. Also, deleted region level rules and its associated groups before deleting the site.

That was easy.

However, what if Global Manager has been deleted before you take out Local Manager from it. 😊

In this case, all your LM’s would continue to try to reach out to GM for configuration sync. No worries, VMware has solutions to every possible problem / situation for its product.

Run the following API at all local mangers in the env to remove the objects,

POST https://172.16.31.130/policy/api/v1/infra/site?action=offboard

Here is the possible output that you would see,

Lets get the status of the above API call,

GET https://172.16.31.130/policy/api/v1/infra/site/offboarding-status

And then the last API is to remove Active / Standby GM from selected LM.

POST https://172.16.31.130/api/v1/sites?action=offboard_local

That’s it for this post. Thank you for reading.

Are you looking out for a lab to practice VMware products…? If yes, then click here to know more about our Lab-as-a-Service (LaaS).

Leave your email address in the box below to receive notification on my new blogs.
VMware Tanzu Supervisor Cluster Deployment Stuck at “Configuring”

Thought of sharing this with you all.

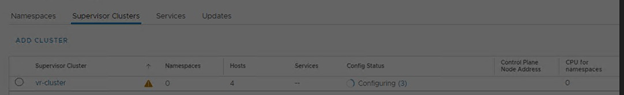
Tanzu Supervisor Cluster Deployment fails and shows “Configuring” for all 3 “SupervisorControlPlaneVM” VM’s.

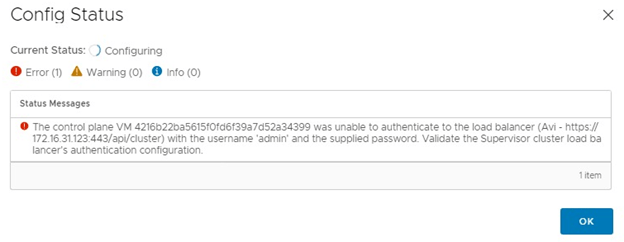
If you click on (3), it shows either of the below warnings / errors.

“Customization operations of the guest OS for Master node VM with identifier vm-XXXX is pending”

In my case, it showed up for a few mins and then I saw an error.

“The control plane VM 42XXXX was unable to authenticate to the load balancer (Avi – https://172.16.31.123:443/api/cluster) with the username ‘admin’ and the supplied password. Validate the Supervisor cluster load balancer’s authentication configuration.”

Even though the supplied credentials were correct.

Looks like this is a known issue if the version of your esxi is 7.0 U3 and you are trying to use Advance Loan Balancer (AVI).

To resolve this issue, I had to change the Authentication settings in AVI.

Login to AVI and Navigate to Admin > Settings & Access Settings

Click on “Edit”

Check the box “Allow Basic Authentication”

Click “Save” and you should be good.

The “Config Status” changes to Running in couple of minutes and you should be good configure it further.

Some of the other workarounds that came across while troubleshooting this issue…

  • Nslookup to all the components in the env to make sure that it resolves to correct name.
  • Check NTP settings on all components (vCenter, ESXi, AVI and NSX) and make sure it syncs to same NTP Server.
  • Check routing between all the additional networks that you have created for Tanzu deployment.

Additionally, you can use the following command on vCenter to check the status / error of the deployment.

tail -f /var/log/vmware/wcp/wcpsvc.log

Changing authentication settings in AVI resolved the issue for me. Your issue may be related to one of the causes that I mentioned above.

Good Luck. Keep Sharing.
That’s all for this blogpost.

Are you looking out for a lab to practice VMware products…? If yes, then click here to know more about our Lab-as-a-Service (LaaS).

Leave your email address in the box below to receive notification on my new blogs.